Website Not Showing on Google? Complete SEO Troubleshooting Guide
A page or site isn’t showing on Google because something may be preventing discovery, crawling, rendering, indexing, canonical selection, or appearance for a particular query — and Google Search Console’s URL Inspection tool can help identify which conditions apply.
The fastest way to diagnose a specific URL is usually the URL Inspection tool in Google Search Console — not guesswork, not a generic checklist, and not repeatedly clicking “Request Indexing.” Requesting indexing is a crawl request; it does not remove an underlying robots.txt block, noindex directive, server error, canonical conflict, or quality issue.
Google does not guarantee that any page will be crawled, indexed, or shown for a particular search, even when the page meets technical requirements. This guide is a diagnostic path to identify the likely cause — not a promise that a particular fix will make a page appear.
The mechanics described here — what Search Console reports, what robots.txt and noindex control, how crawling and rendering work, and how canonicalization affects URLs — are based on Google’s published Search Central and Search Console documentation, linked at first mention and listed in full at the end.
Google commonly describes Google Search in three broad stages: crawling, indexing, and serving. Google also documents rendering and canonicalization as important processes within that broader system. The six-stage sequencing used in this article — Discovery, Crawling, Rendering, Indexing, Canonicalization, and Serving — is therefore SEORAF’s diagnostic model, built from Google’s documentation rather than presented as an official Google process.
This article was fact-checked against Google’s current Search Central and Search Console Help documentation in September 2026.
Website Not Showing on Google? Start Here: Find Your Situation in 60 Seconds
Work through this section before reading a detailed cause below. It’s the fastest route to identifying whether you’re dealing with a site-wide problem, a page-specific problem, or a page that is already indexed but not appearing for the search you expect.
Step 1: Is the problem site-wide or page-specific?
| Signal | Website-level problem | Page-level problem |
|---|---|---|
| Scope in Search Console | Drop or exclusion pattern affects many URLs across the property | A handful of specific URLs, often sharing a template or content pattern |
site: search | Returns few or no results at all | Returns other site pages but not the specific page |
| Typical root causes | Sitewide noindex, broad robots.txt rule, server/access problem, manual action, security issue, DNS/SSL problem | Page-level noindex, orphaned URL, canonical conflict, rendering problem, duplicate or low-value content, template issue |
| Where to check first | Manual Actions report, Security Issues report, robots.txt, server/host status | URL Inspection tool |
A note on the site: operator: it’s a useful rough sanity check, but it isn’t authoritative. Search results and approximate counts do not replace Search Console’s indexing data. Use it as a quick first look, not as proof that a particular URL is or isn’t indexed.
SEORAF’s triage flow for the first 60 seconds of diagnosis. SEORAF diagnostic framework — the sequencing and priority order are SEORAF’s own; the underlying Google reports and tools referenced are Google’s.
Step 2: Check in this priority order
Real sites can have several problems at once. If multiple causes could plausibly apply, start with broad blockers and then move toward page-specific indexing and content questions. The order below is a SEORAF diagnostic priority, not an official Google troubleshooting sequence.
| Priority | Check | Why it comes first | Go to |
|---|---|---|---|
| P0 | Manual Actions report, Security Issues report | These conditions can affect Search visibility and are not ordinary crawl errors. | Security & Manual Actions |
| P1 | robots.txt, noindex, server/fetch errors | These can prevent Google from accessing or indexing a URL. | Access & Crawl Causes, Indexing & Content Causes |
| P2 | Canonical signals, rendering, JavaScript dependency | These become more useful to investigate once basic access is confirmed. | Indexing & Content Causes |
| P3 | Content uniqueness, usefulness, and query relevance | These are broader indexing and serving considerations after technical blockers are ruled out. | Diagnosing in Search Console, Question 8 |
Step 3: Match your symptom
| What you’re seeing | Likely area | Go to |
|---|---|---|
| Page doesn’t appear even when you search its exact URL | Discovery, crawling, rendering, indexing, or canonicalization | Diagnosing in Search Console |
| Page is indexed but doesn’t appear for the keywords you expect | Serving / query relevance | Diagnosing in Search Console, Question 8 |
| Most or all of the site is missing | Possible sitewide access, indexing, enforcement, or security issue | Security & Manual Actions |
| One page is missing, everything else is fine | Page-level issue | Diagnosing in Search Console |
| A page was indexed and visible, then disappeared | Recent technical, content, or indexing change | A Page That Used to Show Up and Stopped |
| Brand-new site, nothing indexed yet | Discovery and normal early-stage crawling/indexing | New Websites |
Key Terms at a Glance
| Term | Definition |
|---|---|
| Crawling | Googlebot requesting and fetching a URL’s content. |
| Rendering | Processing JavaScript-dependent content so Google can understand the rendered page. |
| Indexing | Processing a crawled page and storing information about it in Google’s index so it may be eligible to appear in Search. |
| Canonicalization | Google selecting a representative URL from a group of duplicate or substantially similar URLs. |
| Serving | The process of determining which indexed results are shown for a particular search. |
| SEORAF Six-Stage Indexing Pipeline | SEORAF’s own diagnostic breakdown: Discover → Crawl → Render → Index → Canonicalize → Serve. |
| Discovered – currently not indexed | Google knows about the URL but has not crawled it yet. |
| Crawled – currently not indexed | Google crawled the URL but has not currently indexed it. |
| Soft 404 | A URL that returns a successful HTTP response but appears to Google to represent a missing or empty page. |
| Manual action | A Google enforcement action resulting from a human reviewer determining that pages violate Google’s spam policies. |
| Security issue | A detected security problem such as hacked content, malware, or phishing that can affect how a site is presented in Search. |
How Google Actually Gets a Page Into Search Results
Every fix in this guide maps to one stage of the SEORAF Six-Stage Indexing Pipeline referenced above. It’s SEORAF’s own diagnostic structure, part of our broader Technical SEO coverage — built on top of Google’s documented crawling, indexing, and serving process rather than quoted from Google as an official model.
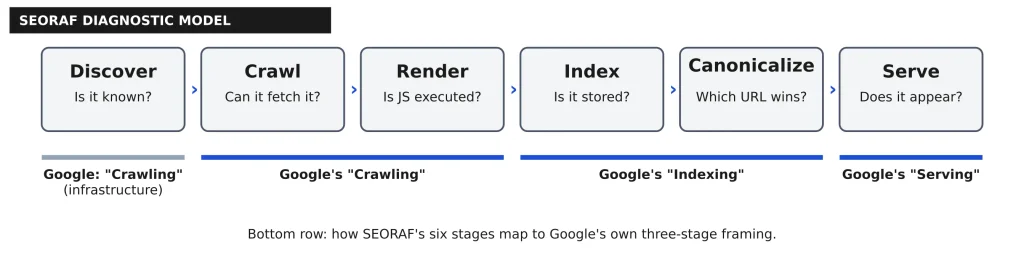
SEORAF’s Six-Stage Indexing Pipeline — our own diagnostic breakdown of Google’s documented crawling, indexing, and serving concepts. SEORAF diagnostic model — not an official Google diagram or official Google terminology.
Discover → Crawl → Render → Index → Canonicalize → Serve
Discover
Google discovers URLs in multiple ways, including links, sitemaps, and other known references. A URL that Google does not yet know about cannot be crawled until it is discovered. Discovery therefore comes before crawling in this diagnostic model, although Google does not publish the six-stage sequence used here.
Crawl
Once a URL is known, Google may request it — but “known” doesn’t mean “immediately fetched.” Google schedules crawling algorithmically based on many factors, including how the site responds to requests. Crawling can also be prevented by robots.txt or disrupted by server and access errors. SEORAF’s Crawling in SEO cluster covers crawl behavior in more depth than this diagnostic guide requires.
Render
A crawled page may depend on JavaScript to expose some of its content or functionality. Google can process JavaScript during rendering so it can understand the resulting page. Rendering is a separate processing step and is not guaranteed to happen immediately after crawling. Because Google uses mobile-first indexing, important content and links should also be available in the mobile version of the page.
Index
Indexing is the processing and storage stage in which Google evaluates information from a crawled page and determines whether the page should be included in its index. Crawling a page does not guarantee indexing. Google can choose not to index pages for several reasons, including duplication, quality considerations, technical directives, and other Search requirements.
Canonicalize
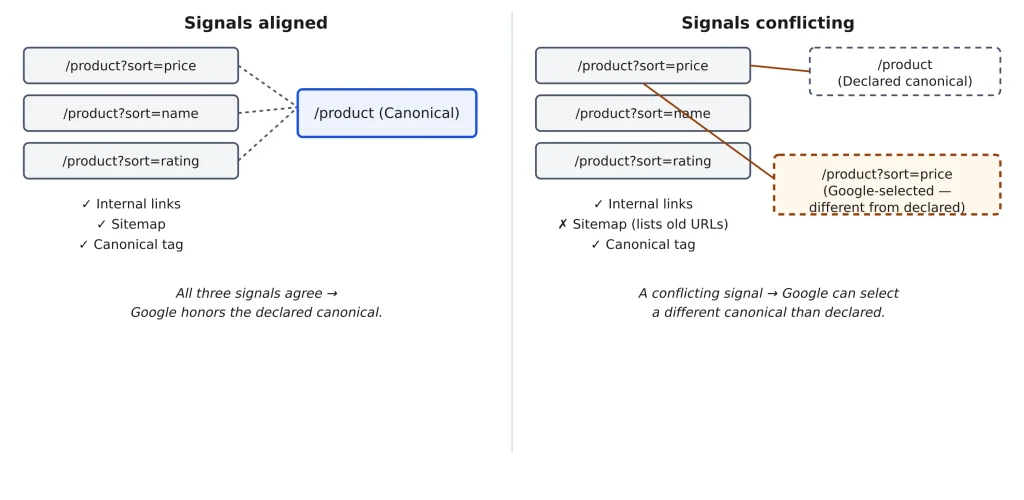
When Google encounters duplicate or substantially similar URLs, it can group them and select a canonical representative. Your declared canonical is a signal, not an absolute instruction. Google can select a different canonical when its other signals indicate another URL is more representative.
Serve
Being indexed does not guarantee appearing for every search. Search results depend on relevance and many other systems and signals. Google states that a URL marked as indexed by URL Inspection can still fail to appear for a particular query. Therefore, a page that is confirmed as indexed but missing for a particular query should be investigated separately from a page that is genuinely not indexed.
Most troubleshooting content treats “not showing on Google” as one undifferentiated problem. A fix aimed at the wrong stage may do nothing — adding content cannot solve a crawl block, and changing a canonical cannot solve a server outage. Diagnosis should therefore start with the conditions that prevent Google from reaching or processing the page and then move toward indexing and query-level visibility.
Diagnosing a Specific Page in Google Search Console
For a handful of URLs, work through the numbered questions below one at a time. If you’re seeing the same issue across dozens or hundreds of URLs, don’t inspect every URL individually: open the Page indexing report, group URLs by exclusion reason, and then inspect representative URLs to confirm the pattern.
Before You Start: The 10-Second Serving Check
Search Google directly for the page’s exact URL, or for a distinctive phrase from its content, logged out. If the page appears, it may already be indexed, so move to Question 8 and investigate whether the problem is query relevance rather than indexing. If it does not appear, use URL Inspection to determine what Google knows about the URL instead of treating the absence from one search as proof that the page is not indexed.
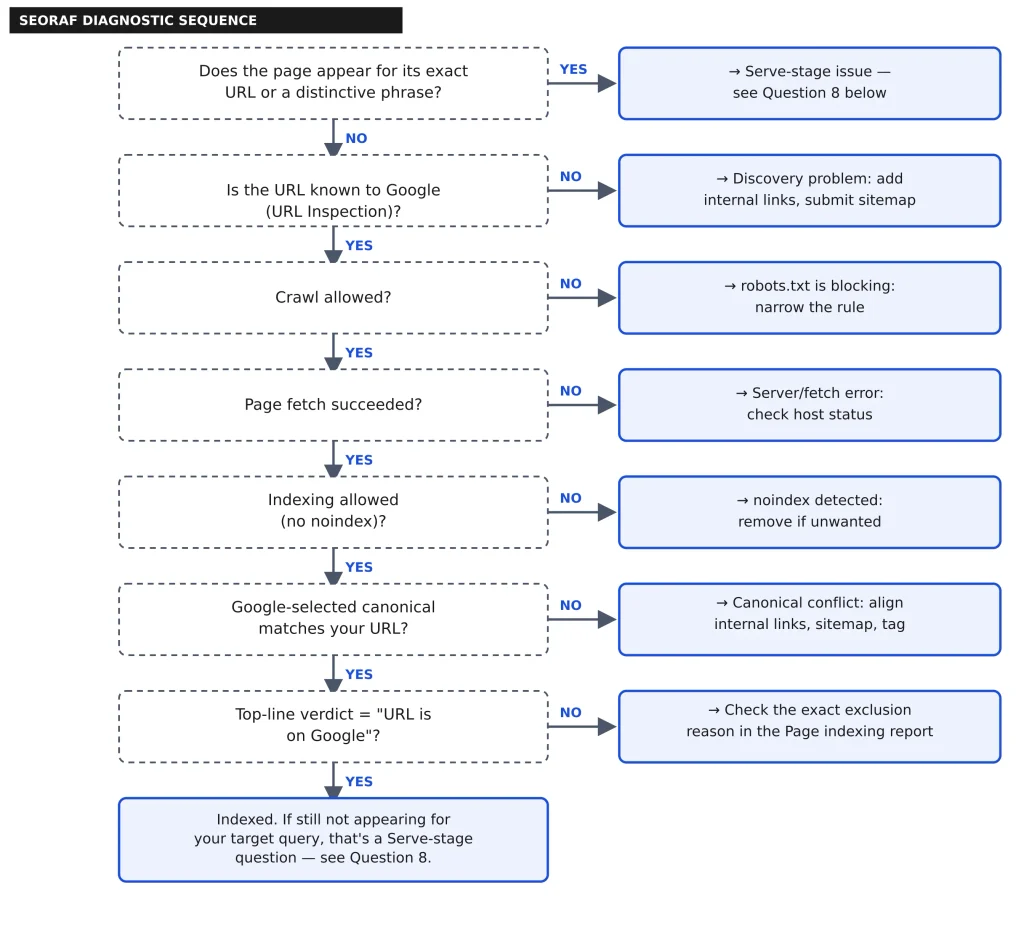
SEORAF’s page-level diagnostic tree. SEORAF diagnostic sequence — the gating order is SEORAF’s model, while the Search Console fields and reports are Google’s.
1. Is Google aware of the site at all?
Confirm you’re looking at the correct verified Search Console property — www versus non-www, and http versus https. A Domain property covers all subdomains and protocol variants within the domain, while a URL-prefix property covers the verified prefix. Monitoring the wrong property can make a healthy site look empty in the data.
Then check the Manual Actions report and Security Issues report when the problem appears site-wide or unusually severe. URL Inspection does not test whether a site is free of manual actions or security issues, so those reports need to be checked separately.
2. Is the URL known to Google?
Run URL Inspection on the exact URL. If Google reports that the URL is unknown, treat discovery as the first problem to investigate. Google can discover URLs through links, sitemaps, and other sources. Add at least one useful internal link from a page Google can already reach, and make sure the URL is appropriately represented in your sitemap if you use one.
This is a discovery improvement, not something that requires repeated indexing requests. For a single important URL, URL Inspection can also be used to request a crawl after the page is accessible and indexable.
3. Can Google crawl it?
Check the Crawl allowed? field. “No” indicates that a robots.txt rule is preventing Google from crawling the URL. Then check Page fetch: a failure can indicate that the server did not respond successfully, timed out, or otherwise prevented Google from fetching the page.
See robots.txt and Server and Accessibility Errors below for the corresponding fixes.
4. Is indexing allowed?
Check Indexing allowed?. If Google detects a noindex directive, the page is being instructed not to appear in Search. The directive can be delivered through a meta tag or an X-Robots-Tag HTTP header.
After removing an unwanted noindex directive, use Test Live URL to verify the current version. If robots.txt prevents Google from fetching the page, Google may not be able to see the noindex change until the crawl block is removed.
5. What canonical did Google select?
Compare User-declared canonical with Google-selected canonical in the indexed URL Inspection data. If they differ, review whether your internal links, sitemap URLs, redirects, and canonical signals consistently identify the same preferred URL. Google can select a different canonical when its signals indicate another URL is more representative.
Do not treat a single canonical mismatch as proof of a technical error. Duplicate and alternate URLs can legitimately be excluded when Google considers another URL the representative version.
6. Is the page indexed?
The URL Inspection report can show statuses such as “URL is on Google” or “URL is not on Google.” “URL is on Google” means the URL has been indexed and can appear in Search, but Google explicitly notes that this does not guarantee that it will appear for every search.
For larger groups of URLs, cross-check the Page indexing report. A single non-indexed URL may be page-specific; many URLs sharing the same reason can reveal a template or sitewide pattern.
7. Is there an indexing exclusion, and what kind?
Open the Why pages aren’t indexed table in the Page indexing report and read the specific reason — for example, “Crawled – currently not indexed,” “Discovered – currently not indexed,” “Excluded by noindex tag,” “Duplicate, Google chose different canonical than user,” “Soft 404,” “Server error (5xx),” or “Blocked by robots.txt.” Each represents a different condition and should be diagnosed according to its actual reason.
Once a reported issue is corrected across the affected URLs, use Validate Fix where the report offers validation. Google says validation typically takes up to about two weeks, although some cases can take longer.
8. Is the page actually searchable for the expected query?
If URL Inspection confirms that the URL is on Google, the question changes from “Why isn’t this URL indexed?” to “Why isn’t this indexed URL appearing for this query?” That can involve relevance, competing results, search context, content quality, or other Search systems.
Test the page with its exact URL or a distinctive phrase, then compare that result with the query for which you expected it to appear. If the page does not appear even for an exact-URL search, return to Question 6 and inspect its current indexed status.
What to Do Once You’ve Confirmed the Cause
Every diagnostic question above should lead to a specific correction when a real issue is found — a robots.txt change, a removed noindex directive, a resolved server error, corrected canonical signals, or another documented fix. Request Indexing is different: it asks Google to crawl a specific URL. It does not itself repair the underlying issue.
Common mistake: requesting indexing repeatedly without changing anything, or trying to use individual requests as a substitute for a sitemap when many URLs need to be discovered or recrawled.
Do this instead: fix the confirmed condition first. Then, for an important individual URL, request indexing if appropriate. For many new or updated URLs, maintain a clean sitemap and let Google discover and recrawl the URLs normally.
| Appropriate | Not appropriate |
|---|---|
| After fixing a confirmed issue on an important individual page | Page is blocked by robots.txt and the block has not been removed |
| A new or substantially updated important page needs an individual crawl request | Page carries an unwanted noindex directive that has not been removed |
| After confirming the live page is accessible and indexable | Trying to submit dozens or hundreds of URLs individually instead of using a sitemap |
| After a substantial update where an individual recrawl request is useful | Using Request Indexing as a substitute for fixing the actual technical problem |
Access & Crawl Causes
These conditions can prevent Google from reaching or successfully processing a URL — P1 in the SEORAF diagnostic priority order above.
robots.txt: What It Actually Controls
robots.txt controls crawler access — it tells compliant crawlers which URLs they may request. It is not a reliable mechanism for keeping a URL out of Google’s index. A URL blocked by robots.txt can still be known to Google and can potentially appear in Search without its content being fetched.
Common mistake: using robots.txt as the only mechanism to prevent a page from appearing in Search, or combining a robots.txt block with a noindex directive and assuming Google will always see the noindex.
Do this instead: if a crawlable page should be excluded from Search, use an appropriate noindex directive and make sure Google can crawl the page well enough to see that directive.
Server and Accessibility Errors
A sustained server or fetch error can prevent Google from successfully retrieving a URL. Check server availability, DNS, CDN behavior, firewall rules, authentication requirements, and other access controls. A security or caching layer can also interfere with Googlebot requests.
Don’t assume the hosting provider is always responsible. The cause can also be a security plugin, CDN rule, application error, DNS configuration, or resource exhaustion under load. For a broader walkthrough of crawl-blocking server responses, see SEORAF’s guide to fixing crawl errors.
Sitemap Checks
An XML sitemap lists URLs you want search engines to discover and can help Google discover URLs efficiently. A sitemap is a discovery aid, not an indexing guarantee.
Confirm that your sitemap is valid, accessible, submitted when appropriate, and primarily contains the canonical URLs you want Google to discover. Keep removed, redirected, blocked, or intentionally non-indexable URLs out of the sitemap.
Google notes that smaller sites with comprehensive internal linking may not need a sitemap, but larger or frequently updated sites can benefit substantially from one. Do not treat sitemap submission as proof that a URL will be indexed.
Crawlability and Internal Linking
Discoverability is whether Google knows a URL exists; crawlability is whether Google can successfully access it once known. Internal linking helps Google discover pages and provides context about the relationship between URLs.
A page with no useful internal links pointing to it can be difficult for Google to discover, even when everything else about the page is technically correct. Link important pages from relevant, crawlable pages using descriptive anchor text, and review link depth for strategically important content on large or complex sites.
Indexing & Content Causes
These become especially useful to investigate once discovery and basic access are confirmed healthy — P2 and P3 in the SEORAF diagnostic priority order.
noindex: The Correct Tool for Exclusion
A noindex meta tag or X-Robots-Tag header tells Google not to index the page. For Google to see a noindex directive, the page must be crawlable; a robots.txt block can prevent Googlebot from fetching the page and therefore from seeing the directive.
Common unwanted sources include a tag left from staging, a CMS or SEO plugin setting, a template-level rule, or a conditional rule affecting pages you did not intend to exclude. Verify the current page using URL Inspection and the live test.
Canonical Tags and Duplicate Content
Google can group duplicate or substantially similar pages into a cluster and select one representative URL — the canonical — to index and serve. Other URLs in the group may not be independently indexed, which is not necessarily an error.
How multiple signals can influence canonical selection. Illustration produced by SEORAF from Google’s documented canonicalization concepts — not an official Google diagram.
| Status | What it means | Is it an error? |
|---|---|---|
| Duplicate without user-selected canonical | The page is a duplicate and no canonical preference was declared; Google selected a representative URL. | No — not necessarily. |
| Duplicate, Google chose different canonical than user | A canonical was declared, but Google selected a different URL as representative. | Not automatically — investigate the signals before deciding whether a correction is needed. |
If your declared and Google-selected canonicals differ, audit whether internal links, sitemap entries, redirects, and canonical tags consistently point toward the URL you want represented. Google can use multiple signals when selecting a canonical, so a declared canonical alone does not guarantee the outcome.
Redirects: 301 vs. 302
Permanent redirects such as 301 and 308 communicate that a move is permanent. Temporary redirects such as 302, 303, and 307 communicate a different intent and may be treated differently. Google can still choose the destination as canonical depending on the overall signals.
Redirect chains and loops can prevent successful crawling or create unnecessary processing. Flatten chains where practical, use a permanent redirect when the move is genuinely permanent, and confirm that the final destination returns a successful response and is indexable when indexing is intended.
404s and Soft 404s
A standard 404 tells browsers and search engines that a page does not exist. A soft 404 is different: the URL returns a successful response but the content appears to represent a missing or empty page.
If content is genuinely gone with no suitable replacement, returning an appropriate 404 or 410 is generally preferable to inventing a redirect. If the content has moved to a clear replacement, redirect the old URL to the relevant destination. Focus cleanup on 404s that matter — particularly URLs you link to internally or include in a sitemap.
JavaScript and Rendering Problems
If a site relies on client-side JavaScript to load meaningful content, Google may need to process that JavaScript during rendering. URL Inspection can show a rendered view and loaded resources, which makes it useful when the raw HTML and rendered page appear substantially different.
Common problems include an initial HTML response containing little meaningful content, critical resources being unavailable, or important content and links being generated only after JavaScript execution. For indexing-critical templates, make important content and navigation available in crawlable HTML wherever practical.
Duplicate and Low-Value Content
Once discovery, crawling, and rendering are functioning, content quality and duplication can become relevant explanations for why a page is not indexed. Google does not use a simple word-count threshold for determining whether a page deserves indexing.
Potential problems include programmatically generated pages with little differentiation, pages that substantially duplicate other pages, and pages offering little additional value. These are content-quality hypotheses to investigate after technical blockers have been ruled out.
Common mistake: padding a page with filler text. Do this instead: add genuinely differentiated information, consolidate near-duplicates when appropriate, or use noindex for variants that do not need independent visibility.
“Crawled – Currently Not Indexed”
This Page indexing report status means Google crawled the page but has not currently indexed it. Google does not provide a single guaranteed cause or timeline for this status. It should therefore be treated as a diagnostic state rather than proof of one specific content problem.
First confirm that the rendered version contains the expected content. Then assess whether the page is substantially differentiated from other relevant pages, whether it is an appropriate canonical candidate, and whether there is a broader pattern affecting similar URLs.
Do not assume that repeated indexing requests are the solution. Fix any confirmed technical or content issue, maintain strong internal linking and sitemap signals where appropriate, and allow Google to recrawl the page.
“Discovered – Currently Not Indexed”
This status means Google knows about the URL but has not yet crawled it. Google may delay crawling for scheduling or resource-management reasons. The status is therefore not automatically evidence that something is technically broken.
A page that exists only in a sitemap, with few internal links, can be harder for Google to discover and prioritize for crawling than a page integrated into a strong internal linking structure. On very large sites, server responsiveness and crawl efficiency can also become relevant.
For a small number of URLs, make sure important pages are linked internally and represented correctly in the sitemap. If a large group remains in this state, investigate site architecture, server response, crawl patterns, and the overall scale of the URL set.
Security Issues and Manual Actions
These are important to check separately because URL Inspection does not test whether a site is free of manual actions or security issues. They are not ordinary crawl errors.
Manual actions occur when a human reviewer determines that pages violate Google’s spam policies. Depending on the issue, a manual action can affect some or many pages. Security issues involve detected security problems such as hacked content, malware, or phishing and can affect how a site is presented in Search.
The response depends on the report. For a manual action, follow the issue-specific remediation instructions and submit a reconsideration request after the violation has been addressed. For a security issue, clean the compromise and follow Google’s security review process.
Special Situations
New Websites
A brand-new site has little or no established crawl history, and Google may need time to discover, crawl, and process its URLs. Google states that it can take time for a new site or page to be discovered and indexed, and there is no fixed timeline that applies to every site.
Make sure the homepage and important pages are reachable through comprehensive internal navigation. Submit a sitemap when appropriate, especially for larger or frequently updated sites, and use URL Inspection for individual important URLs when a direct crawl request is useful.
Common mistake: requesting indexing for dozens of new pages as though repeated requests guarantee faster indexing. Do this instead: build a crawlable site structure, maintain an accurate sitemap where appropriate, and use individual indexing requests selectively.
A Page That Used to Show Up and Stopped
First distinguish an indexing loss from a ranking change. If the page remains indexed but receives less visibility, that is not necessarily an indexing problem. It may involve relevance, competition, content changes, or other Search systems.
If the page genuinely dropped out of the index, investigate what changed around the time visibility disappeared — a CMS or theme update, plugin configuration, redirect, canonical change, noindex directive, content rewrite, migration, or server problem.
Run URL Inspection and compare the current status with the previous expected state. Check Indexing allowed?, the Google-selected canonical, crawl/fetch information, and the Page indexing report. If multiple previously healthy pages disappeared at the same time, check Manual Actions and Security Issues before assuming every page has an independent technical problem.
WordPress-Specific Checks
WordPress introduces several platform-specific causes on top of the general diagnostics above.
Settings → Reading → Search Engine Visibility: WordPress includes an option to discourage search engines from indexing the site. If an entire WordPress site is missing from Search, confirm this setting first.
SEO plugin settings: Yoast SEO, Rank Math, and similar plugins can apply noindex directives to individual posts, pages, taxonomies, or post types. Check the specific page and its SEO settings.
Security or caching plugin robots.txt overrides: some plugins or server layers can generate or modify robots.txt. If a manual change does not persist, identify which system is generating the final response.
Permalink structure changes: changing URL structures can affect many URLs simultaneously. Use appropriate redirects and update internal links and canonical signals during migrations.
Site Migrations
A migration — domain change, protocol change, URL structure change, or CMS change — can introduce redirect, canonical, discovery, and access problems across a site at once.
Before migrating, build a one-to-one URL mapping from important old URLs to their new counterparts. Use permanent redirects when the move is genuinely permanent, update internal links and canonical signals, and monitor both old and new URL sets in Search Console.
Migration timing varies by site size, crawl frequency, and the scale of the change. Google does not publish one fixed timeline for every migration, so treat any specific week-count as an expectation rather than a guarantee.
Common mistake: assuming a migration is complete once redirects go live. Do this instead: update internal links, canonicals, sitemaps, and other URL references so that the new URL structure is consistently represented.
Verification After Fixes
Fixing the underlying cause is only half the process; confirming that Google can now see the corrected version is the other half.
Run Test Live URL in URL Inspection to check whether immediate conditions such as accessibility, robots.txt, and noindex problems have been corrected. Keep in mind that the live test does not test every indexing condition — canonical selection and some Page indexing report statuses require indexed data.
For an issue in the Page indexing report’s Why pages aren’t indexed table, use Validate Fix after the affected instances have been corrected. Google states that validation typically takes up to about two weeks, although it can take longer.
If validation fails, inspect the URLs Google identifies. That can reveal whether the fix was incomplete or whether another instance of the same issue remains.
Common Diagnostic Mistakes
| Mistake | Why it’s wrong | Do this instead |
|---|---|---|
| Requesting indexing repeatedly without changing anything | A request does not repair the underlying technical or content condition. | Fix the confirmed issue first; then request an individual crawl when appropriate. |
| Using robots.txt to keep a page out of results | robots.txt controls crawling, not reliable index exclusion. | Use an appropriate noindex directive when the page should be excluded from Search. |
| Combining a robots.txt block and noindex | If robots.txt blocks crawling, Google may not be able to see the noindex directive. | Keep an intentionally noindexed page crawlable enough for Google to see the directive. |
| Treating “Crawled – currently not indexed” as proof of one specific problem | The status does not identify one universal cause. | Check rendering, duplication, canonical signals, content usefulness, and broader patterns. |
| Assuming a declared canonical will always be honored | Google can select a different canonical based on other signals. | Align internal links, sitemap, redirects, and canonical signals. |
| Diagnosing thin content before checking rendering | Missing rendered content can make a technically useful page appear incomplete. | Compare raw HTML and rendered output first. |
| Treating a ranking drop on an indexed page as an indexing problem | The URL may already be indexed. | Confirm index status first, then investigate relevance and Search visibility. |
| Jumping straight to technical fixes after a sitewide traffic drop | Sitewide visibility changes can have multiple causes. | Check Page indexing, Manual Actions, Security Issues, and recent site changes. |
| Assuming a migration is complete once redirects are live | Old internal links, canonicals, or sitemap URLs can create conflicting signals. | Update all important URL references to the new URLs. |
Summary Table: Status, Cause, and Action
| Search Console status/signal | Diagnostic area | Action |
|---|---|---|
| URL unknown to Google | Discover | Improve discovery with internal links and sitemap coverage where appropriate. |
| Crawl allowed? = No | Crawl | Review and remove or narrow the robots.txt rule if crawling is intended. |
| Page fetch failed | Crawl | Fix server availability, redirects, DNS, firewall, CDN, or other access problems. |
| True 404 | Crawl | Leave it as 404/410 when content is genuinely gone; redirect when a clear replacement exists. |
| Discovered – currently not indexed | Crawl / scheduling | Check internal discovery, sitemap coverage, server responsiveness, and site scale. |
| Rendered content differs materially from expected content | Render | Investigate JavaScript, resource availability, and critical content delivery. |
| Indexing allowed? = No | Index | Remove an unwanted noindex directive and ensure Google can crawl the page. |
| Soft 404 | Index | Return a genuine 404/410 for missing content or restore substantive content. |
| Crawled – currently not indexed | Index | Check rendering, duplication, canonical signals, content usefulness, and broader patterns. |
| Duplicate, Google chose different canonical | Canonicalize | Review all canonical signals and whether the intended URL is actually the best representative. |
| Redirect error | Crawl / redirects | Remove loops and unnecessary chains; make the final destination accessible. |
| URL is on Google, but no visibility for a query | Serve | Investigate query relevance, content, competition, and Search context rather than basic indexing. |
| Manual Actions report entry | Enforcement | Follow the specific remediation instructions and request reconsideration when ready. |
| Security Issues report entry | Security | Clean the affected site and follow Google’s security review process. |
Final Diagnostic Checklist
- Confirmed whether the problem is website-level or page-level
- Checked the Manual Actions report when relevant
- Checked the Security Issues report when relevant
- Confirmed the correct Search Console property is being monitored
- Ran the direct-search sanity check before assuming a technical indexing failure
- Confirmed the page is genuinely unindexed rather than indexed but ranking lower
- Ran URL Inspection on the affected URL(s)
- Recorded the top-line URL Inspection verdict
- Checked Crawl allowed? and Page fetch
- Checked Indexing allowed? for a noindex source
- Compared user-declared and Google-selected canonical where indexed data is available
- Read the exact exclusion reason in the Page indexing report
- Ruled out a rendering or JavaScript problem before concluding that content is low-value
- Checked for a sitewide or template-level pattern when multiple URLs are affected
- Applied a specific fix tied to the confirmed condition
- Used Test Live URL where appropriate
- Used Validate Fix for supported Page indexing issues after correcting affected URLs
- Requested individual indexing selectively rather than repeatedly
A Note on What This Guide Doesn’t Promise
Nothing in this guide guarantees that fixing a given issue will result in a page appearing on Google. Google explicitly distinguishes technical eligibility from actual Search visibility, and URL Inspection itself notes that an indexed URL is not guaranteed to appear for a particular search.
What this guide provides is a diagnostic framework for identifying which condition is most relevant — discovery, crawling, rendering, indexing, canonicalization, or serving — so that the effort is directed toward the actual problem rather than a generic checklist.
This article does not include a firsthand practitioner case study; SEORAF’s standard is to add real, falsifiable firsthand experience only when genuinely available, rather than construct one for the sake of appearing more authoritative. Where this guide goes beyond Google’s documentation — including the Six-Stage Pipeline, the Start Here priority order, and other diagnostic sequencing — that reasoning is explicitly labeled as SEORAF’s own model.
Related SEORAF Guides
- Crawling in SEO — the mechanics of how Google discovers and crawls URLs, including crawl-related concepts.
- Technical SEO Audit — a broader technical health check once indexing-specific causes are ruled out.
- How to Fix Crawl Errors — a deeper walkthrough for sites with server-error or fetch-failure patterns.
- Technical SEO — the broader SEORAF technical SEO coverage.
Sources
- Google Search Central — In-depth guide to how Google Search works
- Google Search Central — Introduction to robots.txt
- Google Search Central — Block Search indexing with noindex
- Google Search Central — Canonicalization / Canonicalization troubleshooting
- Google Search Central — Redirects and Google Search
- Google Search Central — JavaScript SEO basics
- Google Search Central — Sitemaps overview
- Google Search Central — Site moves with URL changes
- Google Search Console Help — Page indexing report
- Google Search Console Help — URL Inspection tool
- Google Search Console Help — Manual actions report
- Google Search Console Help — Security issues report
- Google Search Console Help — Duplicate URLs
- Google Search Console Help — Check and validate a fix
- Google Search Console Help — Inspect and troubleshoot a single page